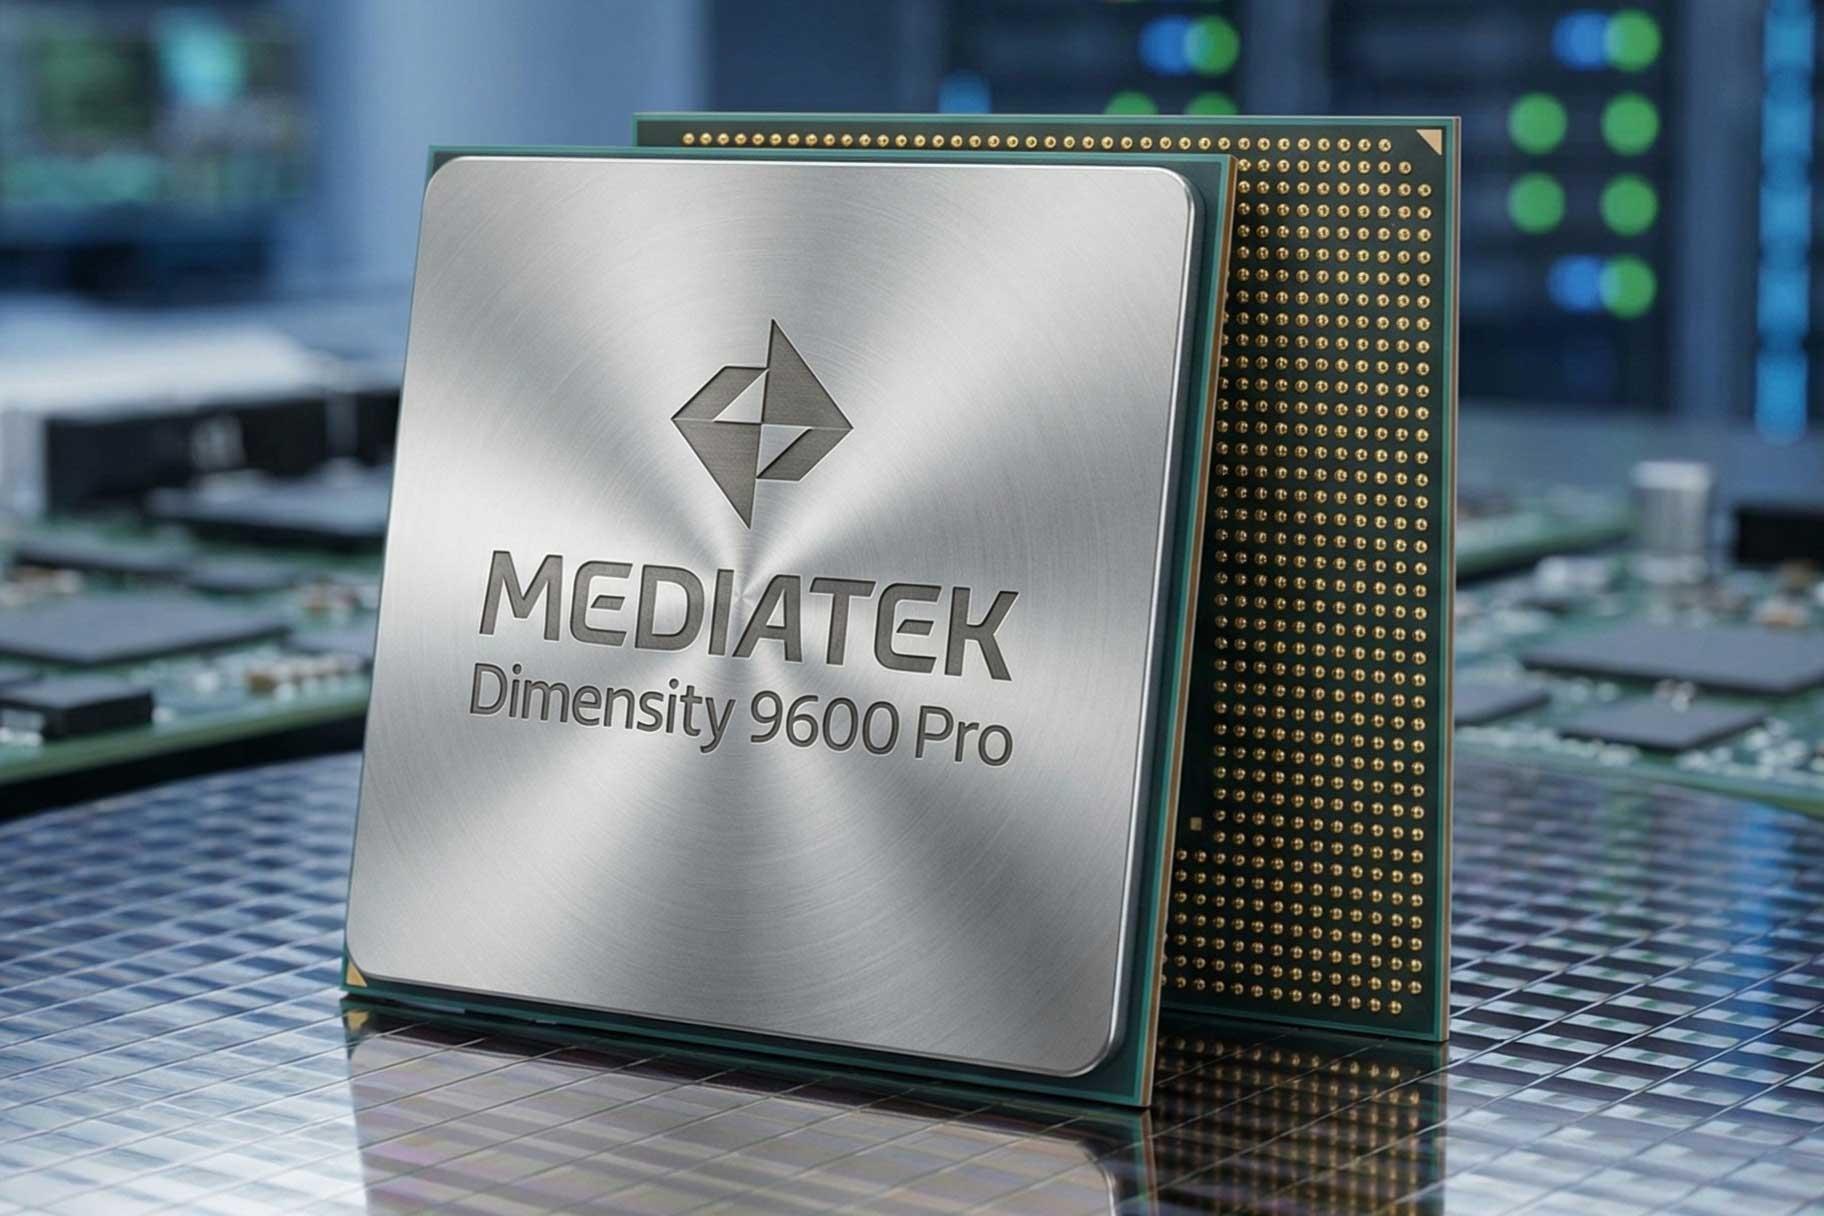
MediaTek’s Dimensity 9600 Pro uses TSMC’s 2nm process and a dual-NPU architecture for generative and agentic workloads. MediaTek reports 51% faster LLM-prefill performance, 55% more token generation per watt and support for models as large as 30 billion parameters.
What changed
Smartphone-class hardware now targets persistent, locally executing agents rather than occasional AI features.
Why it matters
Local inference can improve privacy and latency, but always-on agents introduce battery, permission and cross-application authorization risks.
Practical takeaway
Record whether every inference ran locally or remotely, together with model version, permissions, latency, energy usage and any resulting device action.
Analysis
These performance figures are vendor benchmarks and require validation on shipping devices and realistic thermal conditions.
Published
15 September 2026